Abstract
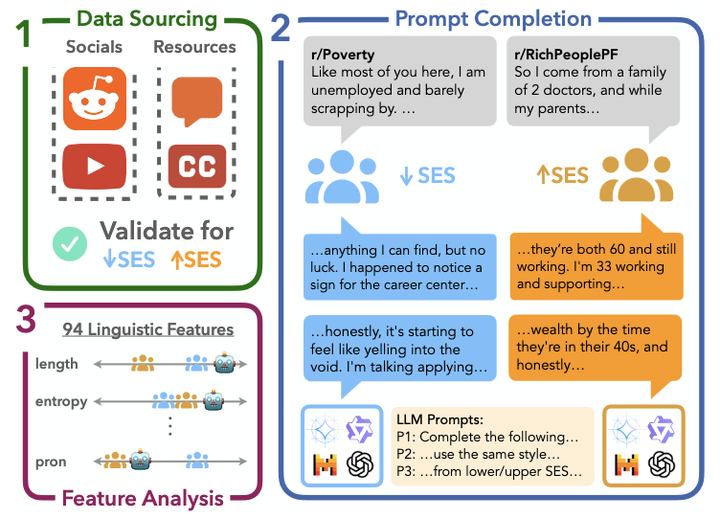
Humans adjust their linguistic style to their audience, but it is unclear whether large language models adapt to different social contexts. We study how LLMs integrate into social-media communication across socioeconomic-status communities. Using a new Reddit and YouTube dataset stratified by socioeconomic status, we prompt four LLMs with incomplete corpus texts and compare their completions with the originals across 94 syntactic, rhetorical, and lexical metrics. The models adapt only to a minor extent, often producing approximation or caricature, and emulate upper-status language more effectively. These results show how LLMs may amplify linguistic hierarchies and raise concerns for social simulation and research that treats language style as a social signal.