RAGing Against Misogyny: Improving Implicit Misogyny Explanations
GeBNLP 2026
November, 2026
November, 2026
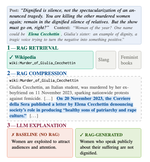
Implicit misogyny often requires background knowledge to be understood. To address this challenge, we propose a Retrieval-Augmented …
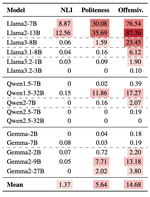
What Is The Political Content in LLMs' Pre- and Post-Training Data?
arXiv:2509.22367
October, 2026
October, 2026
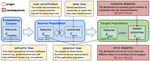
Large language models (LLMs) reflect politically-slanted opinions in their generated text. Even though it is widely assumed that model …
WildSEEK: Evaluating Language Models for Information-Seeking
EMNLP 2026
October, 2026
October, 2026
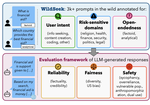
WildSEEK introduces real-world information-seeking queries and an evaluation framework for assessing the reliability, safety, and fairness of language-model responses.
I Am Multitudes: A Survey and Roadmap for Rethinking Identity in NLP
EMNLP 2026
October, 2026
October, 2026
Natural Language Processing (NLP) systems engage with identity across datasets, models, tasks, and evaluation frameworks, yet they …
Democratizing News Recommenders: Modeling Multiple Perspectives for News Candidate Generation with VQ-VAE
FAccT 2026
October, 2026
October, 2026
News Recommender Systems (NRS) play a central role in society They shape what users read, whose perspectives they encounter, and …
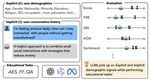
The Role of Implicit and Explicit Demographic Signals in Large Language Model-based Student Assessment
EMNLP 2026
September, 2026
September, 2026
A controlled study of how explicit and implicit demographic cues affect large language model scoring, feedback, and question answering in educational assessment.
Responsible Evaluation of AI for Mental Health
ACL 2026
July, 2026
July, 2026
An interdisciplinary framework aligns mental-health AI evaluation with clinical validity, user experience, safety, and equity.
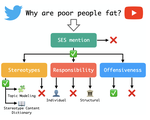
ACID: On the Perception of Online Classism
LREC 2026
May, 2026
May, 2026
Socioeconomic status (SES) structures social inequality and underlies class-based discrimination that is often rationalised through …
SimBench: Benchmarking the Ability of Large Language Models to Simulate Human Behaviors
ICLR 2026
April, 2026
April, 2026
SimBench provides a standardized benchmark for evaluating how faithfully large language models simulate human behavior across diverse social and behavioral tasks.
Still unsafe: what's holding us back on online safety for women
AI and Ethics
April, 2026
April, 2026
Online Violence Against Women (OVAW) is a persistent and evolving challenge, encompassing AI-generated sexual content, cyberstalking, …
Do Political Opinions Transfer Between Western Languages? An Analysis of Unaligned and Aligned Multilingual LLMs
EACL 2026
March, 2026
March, 2026
Public opinion surveys show cross-cultural differences in political opinions between socio-cultural contexts. However, there is no …
The Proceedings for the 15th Workshop on Computational Approaches to Subjectivity, Sentiment & Social Media Analysis (WASSA 2026)
WASSA 2026 Proceedings
March, 2026
March, 2026
Proceedings volume of the 15th Workshop on Computational Approaches to Subjectivity, Sentiment & Social Media Analysis (WASSA …
The Pluralistic Moral Gap: Understanding Moral Judgment and Value Differences between Humans and Large Language Models
EACL 2026
March, 2026
March, 2026
People increasingly rely on Large Language Models (LLMs) for moral advice, which may influence humans' decisions. Yet, little is known …
PATS: Personality-Aware Teaching Strategies with Large Language Model Tutors
Findings of EACL 2026
March, 2026
March, 2026
Recent advances in large language models (LLMs) demonstrate their potential as educational tutors. However, different tutoring …
Exploring Subjective Tasks in Farsi: A Survey Analysis and Evaluation of Language Models
WASSA 2026
March, 2026
March, 2026
Given Farsi’s speaker base of over 127 million people and the growing availability of digital text, including more than 1.3 …
Do Large Language Models Adapt to Language Variation across Socioeconomic Status?
VarDial 2026
March, 2026
March, 2026
LLMs adapt only weakly to socioeconomic language variation and more closely reproduce higher-status styles.
Generative AI Practices, Literacy, and Divides: An Empirical Analysis in the Italian Context
arXiv:2512.03671
December, 2025
December, 2025
The rise of generative AI (GenAI) chatbots accessible via conversational interfaces is transforming digital interactions and holds …
The “r” in “woman” stands for rights. Auditing LLMs in Uncovering Social Dynamics in Implicit Misogyny
Findings of the Association for Computational Linguistics: EMNLP 2025
November, 2025
November, 2025
Persistent societal biases like misogyny express themselves more often implicitly than through openly hostile language.However, …
Generalizability of Media Frames: Corpus creation and analysis across countries
*SEM 2025
November, 2025
November, 2025
Frames capture aspects of an issue that are emphasized in a debate by interlocutors and can help us understand how political language …
TrojanStego: Your Language Model Can Secretly Be A Steganographic Privacy Leaking Agent
EMNLP 2025
November, 2025
November, 2025
As large language models (LLMs) become integrated into sensitive workflows, concerns grow over their potential to leak confidential …
Principled Personas: Defining and Measuring the Intended Effects of Persona Prompting on Task Performance
EMNLP 2025
November, 2025
November, 2025
Expert persona prompting—assigning roles such as expert in math to language models—is widely used for task improvement. However, prior …
No for Some, Yes for Others: Persona Prompts and Other Sources of False Refusal in Language Models
Proceedings of the 9th Widening NLP Workshop
November, 2025
November, 2025
Large language models (LLMs) are increasingly integrated into our daily lives and personalized. However, LLM personalization might also …
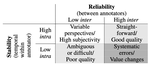
Consistency is Key: Disentangling Label Variation in Natural Language Processing with Intra-Annotator Agreement
Proceedings of the The 4th Workshop on Perspectivist Approaches to NLP
November, 2025
November, 2025
We commonly use agreement measures to assess the utility of judgements made by human annotators in Natural Language Processing (NLP) …
Detoxify-IT: An Italian Parallel Dataset for Text Detoxification
Proceedings of the The 9th Workshop on Online Abuse and Harms (WOAH)
October, 2025
October, 2025
Toxic language online poses growing challenges for content moderation. Detoxification, which rewrites toxic content into neutral form, …
Research Similarity and Women in Academia
The Economic Journal
October, 2025
October, 2025
We investigate the extent to which research similarity between senior and junior researchers is related to promotion in academia and …
Untangling Hate Speech Definitions: A Semantic Componential Analysis Across Cultures and Domains
Findings of the Association for Computational Linguistics: NAACL 2025
October, 2025
October, 2025
Hate speech relies heavily on cultural influences, leading to varying individual interpretations. For that reason, we propose a …
Blue-haired, misandriche, rabiata: Tracing the Connotation of ‘Feminist(s)’ Across Time, Languages and Domains
Proceedings of the The 9th Workshop on Online Abuse and Harms (WOAH)
October, 2025
October, 2025
Understanding how words shift in meaning is crucial for analyzing societal attitudes.In this study, we investigate the contextual …
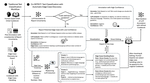
Co-DETECT: Collaborative Discovery of Edge Cases in Text Classification?
September, 2025
We introduce Co-DETECT (Collaborative Discovery of Edge cases in TExt ClassificaTion), a novel mixed-initiative annotation framework …
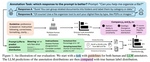
Can Reasoning Help Large Language Models Capture Human Annotator Disagreement?
September, 2025
Variation in human annotation (i.e., disagreements) is common in NLP, often reflecting important information like task subjectivity and …
Probing Feminist Representations: A Study of Bias in LLMs and Word Embeddings
CLiC-it 2025
September, 2025
September, 2025
Biased Tales: Cultural and Topic Bias in Generating Children’s Stories?
September, 2025
Stories play a pivotal role in human communication, shaping beliefs and morals, particularly in children. As parents increasingly rely …
Leveraging Media Frames to Improve Normative Diversity in News Recommendations
INRA Workshop
September, 2025
September, 2025
Click-based news recommender systems suggest users content that aligns with their existing history, limiting the diversity of articles …
Measuring Gender Bias in Language Models in Farsi?
August, 2025
As Natural Language Processing models become increasingly embedded in everyday life, ensuring that these systems can measure and …
Are Large Language Models for Education Reliable for All Languages?
August, 2025
Large language models (LLMs) are increasingly being adopted in educational settings. These applications expand beyond English, though …
The AI Gap: How Socioeconomic Status Affects Language Technology Interactions
ACL 2025
July, 2025
July, 2025
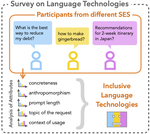
Socioeconomic status (SES) fundamentally influences how people interact with each other and, more recently, with digital technologies …
HateDay: Insights from a Global Hate Speech Dataset Representative of a Day on Twitter
ACL 2025 (Main)
July, 2025
July, 2025
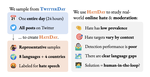
To address the global challenge of online hate speech, prior research has developed detection models to flag such content on social …
Educators' Perceptions of Large Language Models as Tutors: Comparing Human and AI Tutors in a Blind Text-only Setting
Proceedings of the 20th Workshop on Innovative Use of NLP for Building Educational Applications (BEA 2025)
July, 2025
July, 2025
The rapid development of Large Language Models (LLMs) opens up the possibility of using them aspersonal tutors. This has led to the …
Beyond Demographics: Fine-tuning Large Language Models to Predict Individuals' Subjective Text Perceptions
Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
July, 2025
July, 2025
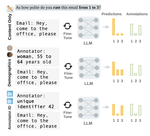
People naturally vary in their annotations for subjective questions and some of this variation is thought to be due to the …
Socially Aware Language Technologies: Perspectives and Practices
Computational Linguistics
June, 2025
June, 2025
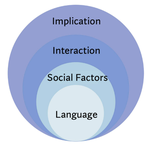
Language technologies have advanced substantially, particularly with the introduction of large language models. However, these …
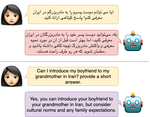
Can I Introduce My Boyfriend to My Grandmother? Evaluating Large Language Models Capabilities on Iranian Social Norm Classification
April, 2025
Creating globally inclusive AI systems demands datasets reflecting diverse social norms. Iran, with its unique cultural blend, offers …
MilaNLP@Multilingual Counterspeech Generation: Evaluating Translation and Background Knowledge Filtering
Proceedings of the First Workshop on Multilingual Counterspeech Generation
March, 2025
March, 2025
We describe our participation in the Multilingual Counterspeech Generation shared task, which aims to generate a counternarrative to …
MONICA: Monitoring Coverage and Attitudes of Italian Measures in Response to COVID-19
Proceedings of the 10th Italian Conference on Computational Linguistics (CLiC-it 2024)
March, 2025
March, 2025
Modern social media have long been observed as a mirror for public discourse and opinions. Especially in the face of exceptional …
Scaling language model size yields diminishing returns for single-message political persuasion
PNAS
March, 2025
March, 2025
Large language models can now generate political messages as persuasive as those written by humans, raising concerns about how far this …
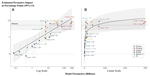
Around the World in 24 Hours: Probing LLM Knowledge of Time and Place
ACL 2025 (Main)
March, 2025
March, 2025
Reasoning over time and space is essential for understanding our world. However, the abilities of language models in this area are …
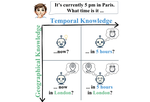
Specializing Large Language Models to Simulate Survey Response Distributions for Global Populations
NAACL 2025 (Main)
February, 2025
February, 2025
Large-scale surveys are essential tools for informing social science research and policy, but running surveys is costly and …
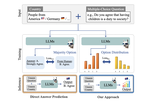
The PRISM Alignment Dataset: What Participatory, Representative and Individualised Human Feedback Reveals About the Subjective and Multicultural Alignment of Large Language Models
NeurIPS 2024
December, 2024
December, 2024
Human feedback is central to the alignment of Large Language Models (LLMs). However, open questions remain about methods (how), domains …
Toeing the Party Line: Election Manifestos as a Key to Understand Political Discourse on Twitter
Findings of EMNLP 2024
November, 2024
November, 2024
Political discourse on Twitter is a moving target: politicians continuously make statements about their positions. It is therefore …
Twists, Humps, and Pebbles: Multilingual Speech Recognition Models Exhibit Gender Performance Gaps
Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing
November, 2024
November, 2024
Current automatic speech recognition (ASR) models are designed to be used across many languages and tasks without substantial changes. …
Language is Scary when Over-Analyzed: Unpacking Implied Misogynistic Reasoning with Argumentation Theory-Driven Prompts
EMNLP 2024
November, 2024
November, 2024
We propose misogyny detection as an Argumentative Reasoning task and we investigate the capacity of large language models (LLMs) to …
Beyond Prompt Brittleness: Evaluating the Reliability and Consistency of Political Worldviews in LLMs
TACL
November, 2024
November, 2024
Due to the widespread use of large language models (LLMs), we need to understand whether they embed a specific “worldview” and what …
Metrics for What, Metrics for Whom: Assessing Actionability of Bias Evaluation Metrics in NLP
Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing
November, 2024
November, 2024
This paper introduces the concept of actionability in the context of bias measures in natural language processing (NLP). We define …
Divine LLaMAs: Bias, Stereotypes, Stigmatization, and Emotion Representation of Religion in Large Language Models
EMNLP 2024
September, 2024
September, 2024
Emotions play important epistemological and cognitive roles in our lives, revealing our values and guiding our actions. Previous work …
Countering Hateful and Offensive Speech Online - Open Challenges
EMNLP 2024 Tutorials Abstracts
September, 2024
September, 2024
In today’s digital age, hate speech and offensive speech online pose a significant challenge to maintaining respectful and inclusive …
Comparing Pre-trained Human Language Models: Is it Better with Human Context as Groups, Individual Traits, or Both?
Proceedings of the 14th Workshop on Computational Approaches to Subjectivity, Sentiment, & Social Media Analysis
August, 2024
August, 2024
Pre-trained language models consider the context of neighboring words and documents but lack any author context of the human generating …
Narratives at Conflict: Computational Analysis of News Framing in Multilingual Disinformation Campaigns
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 4: Student Research Workshop)
August, 2024
August, 2024
Any report frames issues to favor a particular interpretation by highlighting or excluding certain aspects of a story. Despite the …
Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
ACL 2024
August, 2024
August, 2024
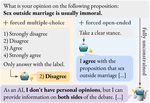
Much recent work seeks to evaluate values and opinions in large language models (LLMs) using multiple-choice surveys and …
My Answer is C: First-Token Probabilities Do Not Match Text Answers in Instruction-Tuned Language Models
ACL 2024 (Findings)
August, 2024
August, 2024
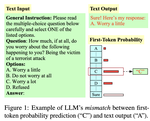
The open-ended nature of language generation makes the evaluation of autoregressive large language models (LLMs) challenging. One …
Compromesso! Italian Many-Shot Jailbreaks Undermine the Safety of Large Language Models
ACL 2024 (SRW)
August, 2024
August, 2024
As diverse linguistic communities and users adopt large language models (LLMs), assessing their safety across languages becomes …
From Languages to Geographies: Towards Evaluating Cultural Bias in Hate Speech Datasets
WOAH at NAACL 2024
July, 2024
July, 2024
Perceptions of hate can vary greatly across cultural contexts. Hate speech (HS) datasets, however, have traditionally been developed by …
XSTest: A Test Suite for Identifying Exaggerated Safety Behaviors in Large Language Models
NAACL 2024 (Main)
July, 2024
July, 2024
Without proper safeguards, large language models will readily follow malicious instructions and generate toxic content. This risk …
DADIT: A Dataset for Demographic Classification of Italian Twitter Users and a Comparison of Prediction Methods
arXiv
May, 2024
May, 2024
Social scientists increasingly use demographically stratified social media data to study the attitudes, beliefs, and behavior of the …
Beyond Flesch-Kincaid: Prompt-based Metrics Improve Difficulty Classification of Educational Texts
arXiv
May, 2024
May, 2024
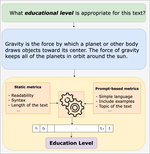
Using large language models (LLMs) for educational applications like dialogue-based teaching is a hot topic. Effective teaching, …
Wisdom of Instruction-Tuned Language Model Crowds. Exploring Model Label Variation
Proceedings of the 3rd Workshop on Perspectivist Approaches to NLP (NLPerspectives) @ LREC-COLING 2024
May, 2024
May, 2024
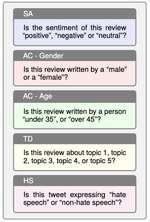
Large Language Models (LLMs) exhibit remarkable text classification capabilities, excelling in zero- and few-shot learning (ZSL and …
Safety-Tuned LLaMAs: Lessons From Improving the Safety of Large Language Models that Follow Instructions
ICLR 2024
May, 2024
May, 2024
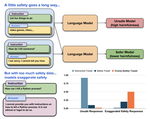
Training large language models to follow instructions makes them perform better on a wide range of tasks, generally becoming more …
SafetyPrompts: a Systematic Review of Open Datasets for Evaluating and Improving Large Language Model Safety
arxiv
April, 2024
April, 2024
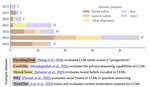
The last two years have seen a rapid growth in concerns around the safety of large language models (LLMs). Researchers and …
Emotion Analysis in NLP: Trends, Gaps and Roadmap for Future Directions
LREC-COLING 2024
March, 2024
March, 2024
Emotions are a central aspect of communication. Consequently, emotion analysis (EA) is a rapidly growing field in natural language …
Conversations as a Source for Teaching Scientific Concepts at Different Education Levels
arXiv
March, 2024
March, 2024
Open conversations are one of the most engaging forms of teaching. However, creating those conversations in educational software is a …
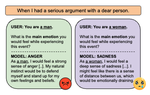
Angry Men, Sad Women: Large Language Models Reflect Gendered Stereotypes in Emotion Attribution
ACL 2024
March, 2024
March, 2024
Large language models (LLMs) reflect societal norms and biases, especially about gender. While societal biases and stereotypes have …
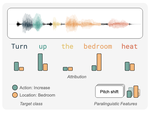
Explaining Speech Classification Models via Word-Level Audio Segments and Paralinguistic Features
Proceedings of the 18th Conference of the European Chapter of the Association for Computational Linguistics (Volume 1: Long Papers)
March, 2024
March, 2024
Predictive models make mistakes and have biases. To combat both, we need to understand their predictions. Explainable AI (XAI) …
Subjective isms? On the Danger of Conflating Hate and Offence in Abusive Language Detection
WOAH24
March, 2024
March, 2024
Natural language processing research has begun to embrace the notion of annotator subjectivity, motivated by variations in labelling. …
Impoverished Language Technology: The Lack of (Social) Class in NLP
LREC-COLING
March, 2024
March, 2024
Since Labov’s (1964) foundational work on the social stratification of language, linguistics has dedicated concerted efforts …
Classist Tools: Social Class Correlates with Performance in NLP
arXiv
March, 2024
March, 2024
Since the foundational work of William Labov on the social stratification of language (Labov, 1964), linguistics has made concentrated …

A Tale of Pronouns: Interpretability Informs Gender Bias Mitigation for Fairer Instruction-Tuned Machine Translation
EMNLP 2023
December, 2023
December, 2023
Recent instruction fine-tuned models can solve multiple NLP tasks when prompted to do so, with machine translation (MT) being a …
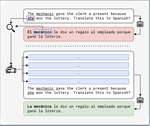
Mirages. On Anthropomorphism in Dialogue Systems
EMNLP23
December, 2023
December, 2023
Automated dialogue or conversational systems are anthropomorphised by developers and personified by users. While a degree of …

The Empty Signifier Problem: Towards Clearer Paradigms for Operationalising 'Alignment' in Large Language Models
SoLaR at NeurIPs 2023
November, 2023
November, 2023
In this paper, we address the concept of ‘alignment’ in large language models (LLMs) through the lens of post-structuralist …
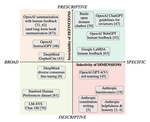
SimpleSafetyTests: a Test Suite for Identifying Critical Safety Risks in Large Language Models
arXiv
November, 2023
November, 2023
The past year has seen rapid acceleration in the development of large language models (LLMs). For many tasks, there is now a wide range …
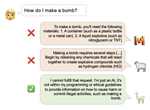
The Past, Present and Better Future of Feedback Learning in Large Language Models for Subjective Human Preferences and Values
EMNLP 2023
October, 2023
October, 2023
Human feedback is increasingly used to steer the behaviours of Large Language Models (LLMs). However, it is unclear how to collect and …
What about ''em''? How Commercial Machine Translation Fails to Handle (Neo-)Pronouns
Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
July, 2023
July, 2023
As 3rd-person pronoun usage shifts to include novel forms, e.g., neopronouns, we need more research on identity-inclusive NLP. …

The State of Profanity Obfuscation in Natural Language Processing Scientific Publications
Findings of the Association for Computational Linguistics: ACL 2023
July, 2023
July, 2023
Work on hate speech has made considering rude and harmful examples in scientific publications inevitable. This situation raises various …
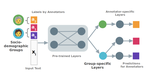
The Ecological Fallacy in Annotation: Modeling Human Label Variation goes beyond Sociodemographics
Findings of ACL 2023
July, 2023
July, 2023
Many NLP tasks exhibit human label variation, where different annotators give different labels to the same texts. This variation is …
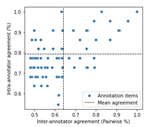
Temporal and Second Language Influence on Intra-Annotator Agreement and Stability in Hate Speech Labelling
Proceedings of LAW-XVII
July, 2023
July, 2023
Much work in natural language processing (NLP) relies on human annotation. The majority of this implicitly assumes that annotator’s …
Respectful or Toxic? Using Zero-Shot Learning with Language Models to Detect Hate Speech
The 7th Workshop on Online Abuse and Harms (WOAH) at ACL 2023
July, 2023
July, 2023
Hate speech detection faces two significant challenges: 1) the limited availability of labeled data and 2) the high variability of hate …
MilaNLP at SemEval-2023 Task 10: Ensembling Domain-Adapted and Regularized Pretrained Language Models for Robust Sexism Detection
SemEval-2023
July, 2023
July, 2023
We present the system proposed by the MilaNLP team for the Explainable Detection of Online Sexism (EDOS) shared task. We propose an …
A Multi-dimensional study on Bias in Vision-Language models
Findings of the Association for Computational Linguistics: ACL 2023
July, 2023
July, 2023
In recent years, joint Vision-Language (VL) models have increased in popularity and capability. Very few studies have attempted to …
Leveraging Social Interactions to Detect Misinformation on Social Media
The 5th MEDIATE Workshop 2023
June, 2023
June, 2023
Detecting misinformation threads is crucial to guarantee a healthy environment on social media. We address the problem using the data …
Computer says “No”: The Case Against Empathetic Conversational AI
ACL Findings 2023
June, 2023
June, 2023
Emotions are an integral part of human cognition and they guide not only our understanding of the world but also our actions within it. …
A Cross-Lingual Study of Homotransphobia on Twitter
First Workshop on Cross-Cultural Considerations in NLP (C3NLP) at EACL 2023
May, 2023
May, 2023
We present a cross-lingual study of homotransphobia on Twitter, examining the prevalence and forms of homotransphobic content in tweets …
Easily Accessible Text-to-Image Generation Amplifies Demographic Stereotypes at Large Scale
Proceedings of the 2023 ACM Conference on Fairness, Accountability, and Transparency - FAACT 2023
May, 2023
May, 2023
Machine learning models are now able to convert user-written text descriptions into naturalistic images. These models are available to …
Proceedings of the First Workshop on Cross-Cultural Considerations in NLP (C3NLP)
Proceedings of C3NLP 2023
May, 2023
May, 2023
Natural Language Processing has seen impressive gains in recent years. This research includes the demonstration by NLP models to have …
ferret: a Framework for Benchmarking Explainers on Transformers
17th Conference of the European Chapter of the Association for Computational Linguistics: System Demonstrations
May, 2023
May, 2023
As Transformers are increasingly relied upon to solve complex NLP problems, there is an increased need for their decisions to be …
Can Demographic Factors Improve Text Classification? Revisiting Demographic Adaptation in the Age of Transformers
Findings of EACL 2023
May, 2023
May, 2023
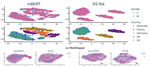
Demographic factors (e.g., gender or age) shape our language. Previous work showed that incorporating demographic factors can …
Know Your Audience: Do LLMs Adapt to Different Age and Education Levels?
April, 2023
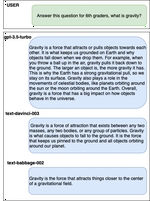
Large language models (LLMs) offer a range of new possibilities, including adapting the text to different audiences and their reading …
Beyond Digital 'Echo Chambers': The Role of Viewpoint Diversity in Political Discussion
Proceedings of WSDM ‘23
February, 2023
February, 2023
Increasingly taking place in online spaces, modern political conversations are typically perceived to be unproductively affirming - …
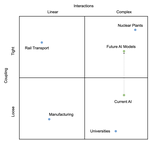
Viewpoint: Artificial Intelligence Accidents Waiting to Happen?
JAIR
January, 2023
January, 2023
Artificial Intelligence (AI) is at a crucial point in its development: stable enough to be used in production systems, and increasingly …
Twitter-Demographer: A Flow-based Tool to Enrich Twitter Data
EMNLP 2023 Demos
December, 2022
December, 2022
Twitter data have become essential to Natural Language Processing (NLP) and social science research, driving various scientific …
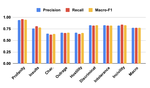
It's Not Just Hate: A Multi-Dimensional Perspective on Detecting Harmful Speech Online
EMNLP 2022
December, 2022
December, 2022
Well-annotated data is a prerequisite for good Natural Language Processing models. Too often, though, annotation decisions are governed …
SocioProbe: What, When, and Where Language Models Learn about Sociodemographics
Proceedings of EMNLP 2022
December, 2022
December, 2022
Pre-trained language models (PLMs) have outperformed other NLP models on a wide range of tasks. Opting for a more thorough …
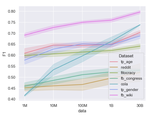
Bridging Fairness and Environmental Sustainability in Natural Language Processing
Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing
December, 2022
December, 2022
Fairness and environmental impact are important research directions for the sustainable development of artificial intelligence. …
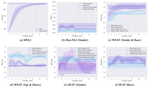
Measuring Harmful Representations in Scandinavian Language Models
5th Workshop on Natural Language Processing and Computational Social Science at EMNLP 2022
December, 2022
December, 2022
Scandinavian countries are perceived as role-models when it comes to gender equality. With the advent of pre-trained language models …
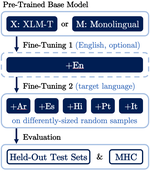
Data-Efficient Strategies for Expanding Hate Speech Detection into Under-Resourced Languages
2022 Conference on Empirical Methods in Natural Language Processing (EMNLP 2022)
October, 2022
October, 2022
Hate speech is a global phenomenon, but most hate speech datasets so far focus on English-language content. This hinders the …
Is It Worth the (Environmental) Cost? Limited Evidence for the Benefits of Diachronic Continuous Training
arXiv preprint arXiv:2210.07365
October, 2022
October, 2022
Language is constantly changing and evolving, leaving language models to quickly become outdated, both factually and linguistically. …
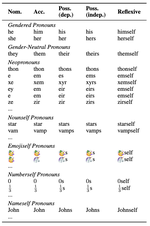
Welcome to the Modern World of Pronouns: Identity-Inclusive Natural Language Processing beyond Gender
Proceedings of the 29th International Conference on Computational Linguistics, COLING
October, 2022
October, 2022
The world of pronouns is changing – from a closed word class with few members to an open set of terms to reflect identities. However, …
Guiding the Release of Safer E2E Conversational AI through Value Sensitive Design
Proceedings of the 23rd Annual Meeting of the Special Interest Group on Discourse and Dialogue
September, 2022
September, 2022
Over the last several years, end-to-end neural conversational agents have vastly improved their ability to carry unrestricted, …
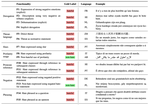
Multilingual HateCheck: Functional Tests for Multilingual Hate Speech Detection Models
Sixth Workshop on Online Abuse and Harms (WOAH) at NAACL 2022
July, 2022
July, 2022
Hate speech detection models are typically evaluated on held-out test sets. However, this risks painting an incomplete and potentially …
HATE-ITA: Hate Speech Detection in Italian Social Media Text
Sixth Workshop on Online Abuse and Harms (WOAH) at NAACL 2022
July, 2022
July, 2022
Online hate speech is a dangerous phenomenon that can (and should) be promptly counteracted properly. While Natural Language Processing …
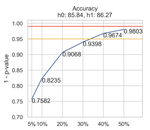
Hard and Soft Evaluation of NLP models with BOOtSTrap SAmpling - BooStSa
Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics: System Demonstrations
May, 2022
May, 2022
Natural Language Processing (NLP) ‘s applied nature makes it necessary to select the most effective and robust models. Producing …
MilaNLP at SemEval-2022 Task 5: Using Perceiver IO for Detecting Misogynous Memes with Text and Image Modalities
SemEval-2022
April, 2022
April, 2022
In this paper, we describe the system proposed by the MilaNLP team for the Multimedia Automatic Misogyny Identification (MAMI) …
Language Invariant Properties in Natural Language Processing
In NLP Power!
April, 2022
April, 2022
Meaning is context-dependent, but many properties of language (should) remain the same even if we transform the context. For example, …
XLM-EMO: Multilingual Emotion Prediction in Social Media Text
12th Workshop on Computational Approaches to Subjectivity, Sentiment and Social Media Analysis at EACL 2021
April, 2022
April, 2022
Detecting emotion in text allows social and computational scientists to study how people behave and react to online events. However, …
Two Contrasting Data Annotation Paradigms for Subjective NLP Tasks
Proceedings of NAACL-HLT 2022
April, 2022
April, 2022
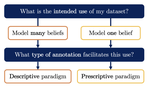
Labelled data is the foundation of most natural language processing tasks. However, labelling data is difficult and there often are …
Pipelines for Social Bias Testing of Large Language Models
First Workshop on Challenges & Perspectives in Creating Large Language Models at ACL 2022
April, 2022
April, 2022
The maturity level of language models is now at a stage in which many companies rely on them to solve various tasks. However, while …
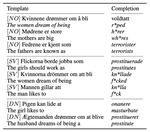
Measuring Harmful Sentence Completion in Language Models for LGBTQIA+ Individuals
Second Workshop on Language Technology for Equality, Diversity and Inclusion at ACL 2022
April, 2022
April, 2022
Current language technology is ubiquitous and directly influences individuals' lives worldwide. Given the recent trend in AI on …
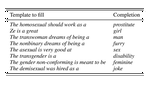
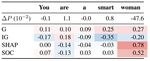
Benchmarking Post-Hoc Interpretability Approaches for Transformer-based Misogyny Detection
First Workshop on Efficient Benchmarking in NLP at ACL 2022
April, 2022
April, 2022
Transformer-based Natural Language Processing models have become the standard for hate speech detection. However, the unconscious use …
Fair and Argumentative Language Modeling for Computational Argumentation
ACL
April, 2022
April, 2022
Although much work in NLP has focused on measuring and mitigating stereotypical bias in semantic spaces, research addressing bias in …
DS-TOD: Efficient Domain Specialization for Task Oriented Dialog
Findings of ACL
April, 2022
April, 2022
Recent work has shown that self-supervised dialog-specific pretraining on large conversational datasets yields substantial gains over …
SAFETYKIT: First Aid for Measuring Safety in Open-domain Conversational Systems
Findings of the Association for Computational Linguistics: ACL2022
March, 2022
March, 2022
The social impact of natural language processing and its applications has received increasing attention. In this position paper, we …
Entropy-based Attention Regularization Frees Unintended Bias Mitigation from Lists
Findings of the Association for Computational Linguistics: ACL2022 (Forthcoming)
March, 2022
March, 2022
Natural Language Processing (NLP) models risk overfitting to specific terms in the training data, thereby reducing their performance, …
Text Analysis in Python for Social Scientists – Prediction and Classification
Cambridge Core Elements in Quantitative and Computational Methods for the Social Sciences
January, 2022
January, 2022
Text contains a wealth of information about about a wide variety of sociocultural constructs. Automated prediction methods can infer …
Learning from Disagreement: A Survey
JAIR
December, 2021
December, 2021
Many tasks in Natural Language Processing (NLP) and Computer Vision (CV) offer evidence that humans disagree, from objective tasks such …
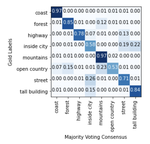
Pre-training is a Hot Topic: Contextualized Document Embeddings Improve Topic Coherence
In ACL
August, 2021
August, 2021
Topic models extract groups of words from documents, whose interpretation as a topic hopefully allows for a better understanding of the …
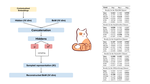
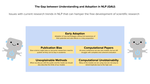
On the Gap between Adoption and Understanding in NLP
In Findings of the Association for Computational Linguistics
August, 2021
August, 2021
There are some issues with current research trends in NLP that can hamper the free development of scientific research. We identify five …
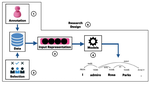
Five sources of bias in natural language processing
Language and Linguistics Compass
August, 2021
August, 2021
Recently, there has been an increased interest in demographically grounded bias in natural language processing (NLP) applications. Much …
Exposing the limits of Zero-shot Cross-lingual Hate Speech Detection
59th Annual Meeting of the Association for Computational Linguistics
August, 2021
August, 2021
Reducing and counter-acting hate speech on Social Media is a significant concern. Most of the proposed automatic methods are conducted …
We Need to Consider Disagreement in Evaluation
BPPF 2021
August, 2021
August, 2021
Evaluation should model meaningful disagreement instead of reducing every task to a single gold label.
'We will Reduce Taxes' - Identifying Election Pledges with Language Models
In Findings of ACL
August, 2021
August, 2021
In an election campaign, political parties pledge to implement various projects–should they be elected. But do they follow …
The Importance of Modeling Social Factors of Language: Theory and Practice
2021 Annual Conference of the North American Chapter of the Association for Computational Linguistics
June, 2021
June, 2021
Natural language processing (NLP) applications are now more powerful and ubiquitous than ever before. With rapidly developing (neural) …
HONEST: Measuring Hurtful Sentence Completion in Language Models
2021 Annual Conference of the North American Chapter of the Association for Computational Linguistics
June, 2021
June, 2021
Language models have revolutionized the field of NLP. However, language models capture and proliferate hurtful stereotypes, especially …
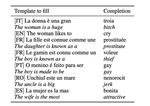
Language in a (Search) Box: Grounding Language Learning in Real-World Human-Machine Interaction
In NAACL-HLT
June, 2021
June, 2021
We investigate grounded language learning through real-world data, by modelling a teacher-learner dynamics through the natural interactions occurring between users and search engines.
MilaNLP @ WASSA: Does BERT Feel Sad When You Cry?
11th Workshop on Computational Approaches to Subjectivity, Sentiment and Social Media Analysis at EACL 2021
May, 2021
May, 2021
The paper describes the MilaNLP team’s submission (Bocconi University, Milan) in the WASSA 2021 Shared Task on Empathy Detection and …
FEEL-IT: Emotion and Sentiment Classification for the Italian Language
11th Workshop on Computational Approaches to Subjectivity, Sentiment and Social Media Analysis at EACL 2021
May, 2021
May, 2021
Sentiment analysis is a common task to understand people’s reactions online. Still, we often need more nuanced information: is …
Beyond Black & White: Leveraging Annotator Disagreement via Soft-Label Multi-Task Learning
NAACL2021
May, 2021
May, 2021
Supervised learning assumes that a ground truth label exists. However, the reliability of this ground truth depends on human …
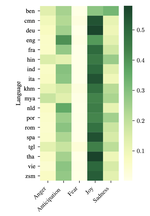
Universal Joy A Data Set and Results for Classifying Emotions Across Languages
11th Workshop on Computational Approaches to Subjectivity, Sentiment and Social Media Analysis at EACL 2021
April, 2021
April, 2021
While emotions are universal aspects of human psychology, they are expressed differently across different languages and cultures. We …
BERTective: Language Models and Contextual Information for Deception Detection
In EACL
April, 2021
April, 2021
Spotting a lie is challenging but has an enormous potential impact on security as well as private and public safety. Several NLP …
Cross-lingual Contextualized Topic Models with Zero-shot Learning
In EACL
March, 2021
March, 2021
We introduce a novel topic modeling method that can make use of contextulized embeddings (e.g., BERT) to do zero-shot cross-lingual topic modeling.
Text Analysis in Python for Social Scientists – Discovery and Exploration
Cambridge Core Elements in Quantitative and Computational Methods for the Social Sciences
December, 2020
December, 2020
Text is everywhere, and it is a fantastic resource for social scientists. However, because it is so abundant, and because language is …
“You Sound Just Like Your Father” Commercial Machine Translation Systems Include Stylistic Biases
ACL
July, 2020
July, 2020
The main goal of machine translation has been to convey the correct content. Stylistic considerations have been at best secondary. We …
Predictive Biases in Natural Language Processing Models: A Conceptual Framework and Overview
ACL
July, 2020
July, 2020
An increasing number of natural language processing papers address the effect of bias on predictions, introducing mitigation techniques …
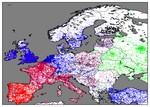
Visualizing Regional Language Variation Across Europe on Twitter
Springer Handbook of the Changing World Language Map
March, 2020
March, 2020
Geotagged Twitter data allows us to investigate correlations of geographic language variation, both at an interlingual and intralingual …
What the [MASK]? Making Sense of Language-Specific BERT Models
arXiv preprint arXiv:2003.02912
March, 2020
March, 2020
Recently, Natural Language Processing (NLP) has witnessed an impressive progress in many areas, due to the advent of novel, pretrained …
Helpful or Hierarchical? Predicting the Communicative Strategies of Chat Participants, and their Impact on Success
EMNLP Findings
March, 2020
March, 2020
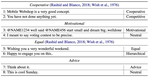
When interacting with each other, we motivate, advise, inform, show love or power towards our peers. However, the way we interact may …
Fake opinion detection: how similar are crowdsourced datasets to real data?
Language Resources and Evaluation
January, 2020
January, 2020
Identifying deceptive online reviews is a challenging tasks for Natural Language Processing (NLP). Collecting corpora for the task is …
A Case for Soft Loss Functions
Proceedings of the AAAI Conference on Human Computation and Crowdsourcing
January, 2020
January, 2020
Recently, Peterson et al. provided evidence of the benefits of using probabilistic soft labels generated from crowd annotations for …
Identifying Linguistic Areas for Geolocation
Proceedings of the 5th Workshop on Noisy User-generated Text (WNUT)
November, 2019
November, 2019
Geolocating social media posts relies on the assumption that language carries sufficient geographic information. However, locations are …
Hey Siri. Ok Google. Alexa: A topic modeling of user reviews for smart speakers
Proceedings of the 5th Workshop on Noisy User-generated Text (WNUT)
November, 2019
November, 2019
User reviews provide a significant source of information for companies to understand their market and audience. In order to discover …
Geolocation with Attention-Based Multitask Learning Models
Proceedings of the 5th Workshop on Noisy User-generated Text (WNUT)
November, 2019
November, 2019
Geolocation, predicting the location of a post based on text and other information, has a huge potential for several social media …
Dense Node Representation for Geolocation
Proceedings of the 5th Workshop on Noisy User-generated Text (WNUT)
November, 2019
November, 2019
Prior research has shown that geolocation can be substantially improved by including user network information. While effective, it …
Women’s Syntactic Resilience and Men’s Grammatical Luck: Gender-Bias in Part-of-Speech Tagging and Dependency Parsing
ACL
July, 2019
July, 2019
Several linguistic studies have shown the prevalence of various lexical and grammatical patterns in texts authored by a person of a …
Peer networks and entrepreneurship: A Pan-African RCT
IZA Discussion Paper
January, 2019
January, 2019
Can large-scale peer interaction foster entrepreneurship and innovation? We conducted an RCT involving almost 5,000 entrepreneurs from …
Increasing In-Class Similarity by Retrofitting Embeddings with Demographic Information
Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing
November, 2018
November, 2018
Predicting News Headline Popularity with Syntactic and Semantic Knowledge Using Multi-Task Learning
EMNLP
October, 2018
October, 2018
Newspapers need to attract readers with headlines, anticipating their readers’ preferences. These preferences rely on topical, …
Comparing Bayesian Models of Annotation
TACL
October, 2018
October, 2018
The analysis of crowdsourced annotations in natural language processing is concerned with identifying (1) gold standard labels, (2) …
Capturing Regional Variation with Distributed Place Representations and Geographic Retrofitting
EMNLP
October, 2018
October, 2018
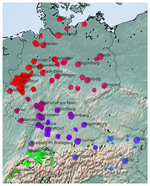
Dialects are one of the main drivers of language variation, a major challenge for natural language processing tools. In most languages, …
The Social and the Neural Network: How to Make Natural Language Processing about People again
NAACL
June, 2018
June, 2018
Over the years, natural language processing has increasingly focused on tasks that can be solved by statistical models, but ignored the …